Most AI projects never ship. We build the ones that do.
We design, build and run practical AI for startups, SMEs and regulated firms — grounded in your own data, inside your own cloud, and safe enough to trust with real work.
Most of the teams we meet aren’t short of ideas. They’re stuck at one of three points — and each one has a different fix.
Compliance can't sign off
Nobody can explain what the model saw, where the data went, or who checked the result. The build was never designed to answer those questions.
Data wasn't ready
Idea was sound, but the data was messy and spread across systems — so every result looked plausible and none could be trusted.
Demo never shipped
A prototype impressed the board, then met real data and real costs. Nobody had priced the production version, so it quietly died.
CAPABILITIES
What we build
Six things, described as what they do rather than what they’re called. Timeframes are typical for a first production release, not a demo.
6–10 weeks
Agentic workflows
Software that looks at a situation, decides what to do, and does it — diagnose a problem, create the job, tell the right person. Built on Franklin, our own AI platform.
What you get
A working agent in your own cloud account, with full audit logging and a rollback path.
4–8 weeks
Answers grounded in your own data
Ask a question and get an answer that points to a real document your team can open and check — instead of a confident guess.
What you get
A retrieval service, a scored evaluation set and a measured accuracy baseline.
4–8 weeks
Document and data extraction
Turn PDFs, forms and emails into clean records your systems can use, with anything unclear sent to a person to check.
What you get
An extraction pipeline with confidence scoring and exception handling.
6–12 weeks
AI features inside your product
Summarising, sorting and assisting, built into the product your customers already use — not bolted on as a separate tool.
What you get
Features shipped behind flags, with usage and cost telemetry from day one.
4–10 weeks
Intelligence in an existing estate
Add AI to established Java, .NET and legacy platforms without a full rewrite — the hard part most vendors quietly avoid.
What you get
An integration layer, documented API contracts and load-tested throughput.
2–3 weeks
Readiness and data foundations
Before you build: what’s actually worth doing, what it will cost to run, and what your data needs first. Often the cheapest thing we do.
What you get
A prioritised shortlist of use cases, scored on value, effort and risk.
GOVERNANCE & TRUST
Built for organisations that have to answer questions
We work with financial services and regulated firms, so this isn’t an appendix. It’s how the build is shaped from step 01.
Your cloud, your account
Deployed into your own AWS account by default, so your data stays inside your existing security boundary and your existing audit scope.
Your data isn’t training anyone’s model
Client data is not used to train or fine-tune models for anyone else, and we’ll put that in writing before work starts.
Versioned prompts, models and config
Every prompt, model version and configuration change lives in source control, so you can see exactly what changed and when.
Human in the loop by design
We agree which decisions need a person before we build — not after an incident makes the answer obvious.
Evaluation you can hand to an auditor
A documented test set, scored results, and a record of how performance moved between versions.
Regulatory readiness
Documentation structured for EU AI Act risk classification and the operational resilience questions your regulator is likely to ask.
OUR APPROACH
Five steps, four gates
Every step ends with a question that has a real “no” available. Step 03 is the one that matters: it’s where we recommend stopping if the numbers don’t hold up.
Step 1
Frame
We define the use case, the data it depends on, and what “good” means as a number you’d be willing to be measured against.
Gate
Is there a measurable outcome worth building?
Step 2
Prototype
A narrow working version, running against your real data. Not a sandbox demo with hand-picked examples.
Gate
Does it hold up on the messy cases, not just the clean ones?
Step 3
Evaluate
We score accuracy, latency, cost per transaction and failure modes against the baseline agreed in stage 01.
Gate
Does it beat the current process on the numbers?
Step 4
Harden
Security review, observability, guardrails, human-in-the-loop design, load testing and cost controls before anything faces a customer.
Gate
Would you be comfortable with this running unattended overnight?
Step 5
Operate
Monitoring for drift and spend, evaluation on a schedule, and model upgrades that don’t quietly regress what already worked.
Ongoing
Is it still doing what it did on day one?
PLATFORM
What it’s built on
Engineering-grade by default. The same stack our delivery teams already run in production — [CONFIRM] trim this list to what we can genuinely stand behind.
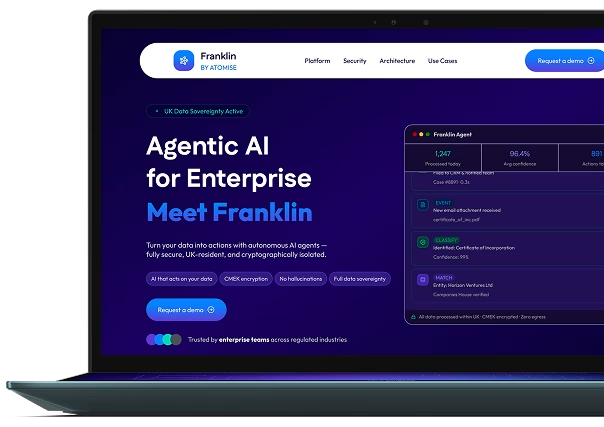
Franklin is our managed agentic RAG platform for regulated industries. It reasons over your data, decides what to do, and acts — inside your cloud, with the data staying where your regulator expects it to stay. We don’t start client agentic work from a blank repository. We start from a platform we build, run and customise ourselves, then shape it around your systems and your approval rules.
Will our data be used to train someone else's model?
No. Your data is never used to train or fine-tune models for anyone else, and we put that in writing before work starts. It stays inside your own cloud account.
Can this run inside our own cloud account?
Yes — by default. We deploy into your own AWS account, so your data stays inside your existing security boundary and region. UK-only setups are supported where that matters.
What if our data isn't clean enough?
That’s common, and fixable. Our short readiness engagement tells you what’s realistic, what it will cost to run, and what your data needs first — before you commit to a build.
How do you stop it making things up?
We ground answers in your own documents, so every reply points to a source you can check. We test accuracy against a real baseline and send low-confidence cases to a person.
What does this cost to run, not just to build?
We measure the cost per use during testing and won’t go ahead if the numbers don’t add up. Everything we ship reports its own usage and cost from day one.
Do we need to hire a data science team afterwards?
No. We build on Franklin, our own platform, and hand over something your existing engineers can run — with clear documentation and a safe way to roll back.
Find out whether AI is worth it for you
A 30-minute call with a senior engineer. We’ll pressure-test the use case you have in mind, tell you what it would realistically take, and say so if the honest answer is “not yet”.
Thank you for requesting to download our Free SME-Systems-Health-Checklist You will receive an email link to download the PDF, we hope you find it useful.